Parallel Renderer
A Monte Carlo path tracer in C++20, built to compare how four ways of splitting an image across CPU threads scale.
- C++20
- std::thread
- OpenMP
- SDL3
- Dear ImGui
- ImPlot
- CMake
- CTest
key results
- 13.29×speedup at 16 threads with the atomic tile index (474.9 → 35.7 ms), 83.1% efficiency
- 13.16×OpenMP schedule(dynamic) at 16 threads, 82.3% efficiency
- 1.57×dynamic over static at 16 threads (33.5 vs. 52.6 ms, 2026-10-23 sweep)
- serial = OpenMPframebuffers match across 6 tiles in CTest, plus a golden image hash
demo
media
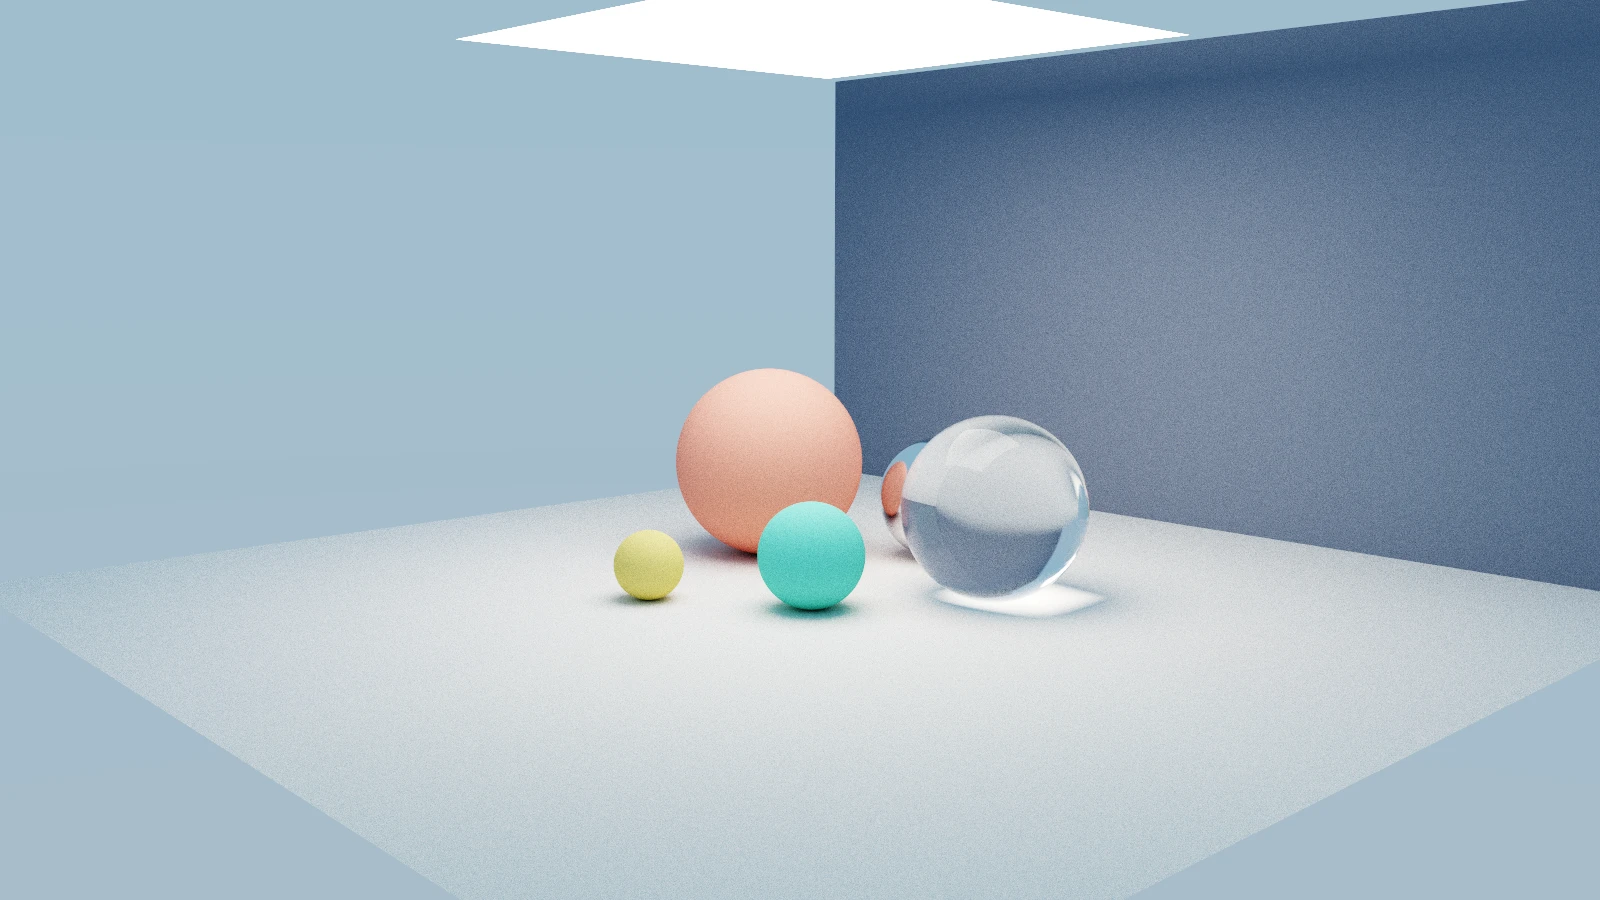
how it works
four schedules
The image is split into 32 px tiles, and each schedule hands tiles to threads differently:
- serial: one thread renders every tile.
- static: each
std::threadgets a fixed, contiguous block of tiles. - dynamic: threads take the next tile from a shared, lock-free atomic tile index
(
std::atomic<int>::fetch_add), so a thread that finishes early picks up more. - openmp:
#pragma omp parallel for schedule(dynamic)over the tiles.
benchmark
The medium scene renders at 800×450 with 16 samples per pixel, depth 8, 32 px tiles and
seed 123. Each configuration runs 5 times and the median counts. The machine: an AMD
Ryzen 9 9950X3D (16 cores, 32 threads) on WSL2 Ubuntu 24.04, GCC 13.3 at -O3.
In the 2026-09-01 reference run, serial takes 474.9 ms and dynamic 35.7 ms at 16 threads, a 13.29× speedup (83.1% efficiency); OpenMP reaches 13.16× (82.3%). A 2026-10-23 sweep added static on the medium scene: its efficiency falls from 90.9% at 2 threads to 55.6% at 16, where dynamic is 1.57× faster. Tiles cost different amounts to render, so a fixed split leaves some threads idle while others finish. The results page charts every run.
same image, any schedule
Each sample’s random numbers are seeded from the seed, the pixel and the sample index, so the image doesn’t depend on which thread renders which tile. CTest checks serial against OpenMP on an image split into 6 tiles, and the serial image against a golden FNV-1a hash; both pass. A serial-vs-dynamic check exists too, but its test image fits in a single tile, so it doesn’t yet exercise the atomic scheduler.
the rest
- A dependency-free PNG encoder: CRC-32, Adler-32 and a stored-deflate zlib stream.
- A GUI with a live tile viewer colored by worker, and ImPlot charts of speedup, runtime and efficiency.
what i'd do next
- Make the serial-vs-dynamic test span several tiles, so it checks the atomic scheduler.
- Add a BVH, so heavier scenes are worth benchmarking.
- Profile the 16-thread runs to see where the remaining efficiency goes.
- Compile the renderer to WebAssembly so the tile viewer can run on this site.