< parallel renderer

scaling results

How each schedule scales from 1 to 16 threads, from the renderer's committed benchmark CSVs. Medians of 5 runs; speedup is against each sweep's own serial, one-thread median.

setup

800×450, 16 samples per pixel, depth 8, 32 px tiles, seed 123, 5 runs per configuration. AMD Ryzen 9 9950X3D (16 cores, 32 threads), WSL2 Ubuntu 24.04, GCC 13.3, -O3. Efficiency is speedup divided by thread count. The dashed line is perfect scaling.

medium scene, 2026-09-01 (reference)

The reference run for dynamic and OpenMP. Static wasn’t run on the medium scene that day. Serial baseline: 474.9 ms.

Speedup vs. threads
serial, 1 thread: 474.9 ms, 1.00× speedup, 100.0% efficiencyserial, 2 threads: 475.7 ms, 1.00× speedup, 49.9% efficiencyserial, 4 threads: 475.9 ms, 1.00× speedup, 24.9% efficiencyserial, 8 threads: 475.3 ms, 1.00× speedup, 12.5% efficiencyserial, 16 threads: 475.1 ms, 1.00× speedup, 6.2% efficiencydynamic, 1 thread: 477.8 ms, 0.99× speedup, 99.4% efficiencydynamic, 2 threads: 240.6 ms, 1.97× speedup, 98.7% efficiencydynamic, 4 threads: 122.0 ms, 3.89× speedup, 97.3% efficiencydynamic, 8 threads: 62.5 ms, 7.59× speedup, 94.9% efficiencydynamic, 16 threads: 35.7 ms, 13.29× speedup, 83.1% efficiencyopenmp, 1 thread: 478.4 ms, 0.99× speedup, 99.3% efficiencyopenmp, 2 threads: 240.5 ms, 1.97× speedup, 98.7% efficiencyopenmp, 4 threads: 139.0 ms, 3.42× speedup, 85.4% efficiencyopenmp, 8 threads: 61.7 ms, 7.70× speedup, 96.2% efficiencyopenmp, 16 threads: 36.1 ms, 13.16× speedup, 82.3% efficiency
Efficiency vs. threads
dynamic, 1 thread: 477.8 ms, 0.99× speedup, 99.4% efficiencydynamic, 2 threads: 240.6 ms, 1.97× speedup, 98.7% efficiencydynamic, 4 threads: 122.0 ms, 3.89× speedup, 97.3% efficiencydynamic, 8 threads: 62.5 ms, 7.59× speedup, 94.9% efficiencydynamic, 16 threads: 35.7 ms, 13.29× speedup, 83.1% efficiencyopenmp, 1 thread: 478.4 ms, 0.99× speedup, 99.3% efficiencyopenmp, 2 threads: 240.5 ms, 1.97× speedup, 98.7% efficiencyopenmp, 4 threads: 139.0 ms, 3.42× speedup, 85.4% efficiencyopenmp, 8 threads: 61.7 ms, 7.70× speedup, 96.2% efficiencyopenmp, 16 threads: 36.1 ms, 13.16× speedup, 82.3% efficiency
table
medium scene, 2026-09-01 (reference): medians of 5 runs
schedulethreadsmedian msrange msspeedupefficiency
serial1474.896474.611–477.1261.00×100.0%
serial2475.739475.411–481.7841.00×49.9%
serial4475.933475.261–480.1241.00×24.9%
serial8475.331475.111–476.8611.00×12.5%
serial16475.066474.677–476.2101.00×6.2%
dynamic1477.758477.626–478.7950.99×99.4%
dynamic2240.590239.553–241.6121.97×98.7%
dynamic4121.996121.734–122.8543.89×97.3%
dynamic862.54261.892–63.0307.59×94.9%
dynamic1635.73534.947–37.21313.29×83.1%
openmp1478.357477.642–491.3150.99×99.3%
openmp2240.506240.307–241.8531.97×98.7%
openmp4138.983121.338–139.0883.42×85.4%
openmp861.68661.283–62.6427.70×96.2%
openmp1636.08635.369–37.93013.16×82.3%

medium scene, 2026-10-23 (with static)

All four schedules in one sweep, so static can be compared directly. Dynamic and OpenMP came out 3–7% faster than on 2026-09-01, within run-to-run variation on WSL2; the 2026-09-01 numbers stay the reference. Serial baseline: 468.6 ms.

Speedup vs. threads
serial, 1 thread: 468.6 ms, 1.00× speedup, 100.0% efficiencyserial, 2 threads: 465.9 ms, 1.01× speedup, 50.3% efficiencyserial, 4 threads: 464.4 ms, 1.01× speedup, 25.2% efficiencyserial, 8 threads: 462.6 ms, 1.01× speedup, 12.7% efficiencyserial, 16 threads: 464.9 ms, 1.01× speedup, 6.3% efficiencystatic, 1 thread: 465.4 ms, 1.01× speedup, 100.7% efficiencystatic, 2 threads: 257.8 ms, 1.82× speedup, 90.9% efficiencystatic, 4 threads: 179.4 ms, 2.61× speedup, 65.3% efficiencystatic, 8 threads: 101.9 ms, 4.60× speedup, 57.5% efficiencystatic, 16 threads: 52.6 ms, 8.90× speedup, 55.6% efficiencydynamic, 1 thread: 466.6 ms, 1.00× speedup, 100.4% efficiencydynamic, 2 threads: 234.0 ms, 2.00× speedup, 100.1% efficiencydynamic, 4 threads: 117.6 ms, 3.99× speedup, 99.7% efficiencydynamic, 8 threads: 59.6 ms, 7.86× speedup, 98.3% efficiencydynamic, 16 threads: 33.5 ms, 13.99× speedup, 87.5% efficiencyopenmp, 1 thread: 466.1 ms, 1.01× speedup, 100.5% efficiencyopenmp, 2 threads: 232.8 ms, 2.01× speedup, 100.6% efficiencyopenmp, 4 threads: 117.1 ms, 4.00× speedup, 100.0% efficiencyopenmp, 8 threads: 59.3 ms, 7.90× speedup, 98.7% efficiencyopenmp, 16 threads: 35.5 ms, 13.21× speedup, 82.6% efficiency
Efficiency vs. threads
static, 1 thread: 465.4 ms, 1.01× speedup, 100.7% efficiencystatic, 2 threads: 257.8 ms, 1.82× speedup, 90.9% efficiencystatic, 4 threads: 179.4 ms, 2.61× speedup, 65.3% efficiencystatic, 8 threads: 101.9 ms, 4.60× speedup, 57.5% efficiencystatic, 16 threads: 52.6 ms, 8.90× speedup, 55.6% efficiencydynamic, 1 thread: 466.6 ms, 1.00× speedup, 100.4% efficiencydynamic, 2 threads: 234.0 ms, 2.00× speedup, 100.1% efficiencydynamic, 4 threads: 117.6 ms, 3.99× speedup, 99.7% efficiencydynamic, 8 threads: 59.6 ms, 7.86× speedup, 98.3% efficiencydynamic, 16 threads: 33.5 ms, 13.99× speedup, 87.5% efficiencyopenmp, 1 thread: 466.1 ms, 1.01× speedup, 100.5% efficiencyopenmp, 2 threads: 232.8 ms, 2.01× speedup, 100.6% efficiencyopenmp, 4 threads: 117.1 ms, 4.00× speedup, 100.0% efficiencyopenmp, 8 threads: 59.3 ms, 7.90× speedup, 98.7% efficiencyopenmp, 16 threads: 35.5 ms, 13.21× speedup, 82.6% efficiency
table
medium scene, 2026-10-23 (with static): medians of 5 runs
schedulethreadsmedian msrange msspeedupefficiency
serial1468.605465.615–470.8961.00×100.0%
serial2465.854462.349–467.2961.01×50.3%
serial4464.394461.343–468.0141.01×25.2%
serial8462.561460.414–463.8141.01×12.7%
serial16464.864461.697–469.0851.01×6.3%
static1465.352463.594–467.9061.01×100.7%
static2257.821257.144–259.7731.82×90.9%
static4179.446179.156–179.7622.61×65.3%
static8101.924101.159–102.6094.60×57.5%
static1652.64651.656–57.8308.90×55.6%
dynamic1466.615464.261–566.8381.00×100.4%
dynamic2233.961231.975–239.1832.00×100.1%
dynamic4117.558117.039–118.0243.99×99.7%
dynamic859.61159.389–59.7807.86×98.3%
dynamic1633.48933.103–34.53913.99×87.5%
openmp1466.092464.823–472.7691.01×100.5%
openmp2232.807232.327–249.8012.01×100.6%
openmp4117.101116.887–117.3334.00×100.0%
openmp859.33259.262–60.2957.90×98.7%
openmp1635.47734.461–36.59813.21×82.6%

simple scene, 2026-09-01

A lighter scene, up to 8 threads. Its numbers aren’t comparable with the medium scene’s. Serial baseline: 189.7 ms.

Speedup vs. threads
serial, 1 thread: 189.7 ms, 1.00× speedup, 100.0% efficiencyserial, 2 threads: 190.2 ms, 1.00× speedup, 49.9% efficiencyserial, 4 threads: 189.9 ms, 1.00× speedup, 25.0% efficiencyserial, 8 threads: 190.2 ms, 1.00× speedup, 12.5% efficiencystatic, 1 thread: 190.4 ms, 1.00× speedup, 99.6% efficiencystatic, 2 threads: 123.4 ms, 1.54× speedup, 76.9% efficiencystatic, 4 threads: 85.1 ms, 2.23× speedup, 55.7% efficiencystatic, 8 threads: 46.6 ms, 4.07× speedup, 50.9% efficiencydynamic, 1 thread: 195.3 ms, 0.97× speedup, 97.2% efficiencydynamic, 2 threads: 96.2 ms, 1.97× speedup, 98.6% efficiencydynamic, 4 threads: 48.5 ms, 3.91× speedup, 97.8% efficiencydynamic, 8 threads: 25.3 ms, 7.49× speedup, 93.6% efficiencyopenmp, 1 thread: 194.7 ms, 0.97× speedup, 97.5% efficiencyopenmp, 2 threads: 96.2 ms, 1.97× speedup, 98.6% efficiencyopenmp, 4 threads: 48.2 ms, 3.94× speedup, 98.5% efficiencyopenmp, 8 threads: 24.8 ms, 7.64× speedup, 95.5% efficiency
Efficiency vs. threads
static, 1 thread: 190.4 ms, 1.00× speedup, 99.6% efficiencystatic, 2 threads: 123.4 ms, 1.54× speedup, 76.9% efficiencystatic, 4 threads: 85.1 ms, 2.23× speedup, 55.7% efficiencystatic, 8 threads: 46.6 ms, 4.07× speedup, 50.9% efficiencydynamic, 1 thread: 195.3 ms, 0.97× speedup, 97.2% efficiencydynamic, 2 threads: 96.2 ms, 1.97× speedup, 98.6% efficiencydynamic, 4 threads: 48.5 ms, 3.91× speedup, 97.8% efficiencydynamic, 8 threads: 25.3 ms, 7.49× speedup, 93.6% efficiencyopenmp, 1 thread: 194.7 ms, 0.97× speedup, 97.5% efficiencyopenmp, 2 threads: 96.2 ms, 1.97× speedup, 98.6% efficiencyopenmp, 4 threads: 48.2 ms, 3.94× speedup, 98.5% efficiencyopenmp, 8 threads: 24.8 ms, 7.64× speedup, 95.5% efficiency
table
simple scene, 2026-09-01: medians of 5 runs
schedulethreadsmedian msrange msspeedupefficiency
serial1189.742188.725–190.6721.00×100.0%
serial2190.247189.734–191.1461.00×49.9%
serial4189.950189.817–191.4521.00×25.0%
serial8190.155189.981–190.2971.00×12.5%
static1190.437190.345–190.7421.00×99.6%
static2123.359123.217–146.6921.54×76.9%
static485.13484.990–85.8242.23×55.7%
static846.58146.113–48.9434.07×50.9%
dynamic1195.287194.854–195.9300.97×97.2%
dynamic296.24595.771–96.7201.97×98.6%
dynamic448.49448.456–48.6353.91×97.8%
dynamic825.34224.754–27.1017.49×93.6%
openmp1194.686194.346–195.6090.97×97.5%
openmp296.21496.025–97.0251.97×98.6%
openmp448.18248.153–48.2513.94×98.5%
openmp824.82924.314–25.0067.64×95.5%

the image

Every schedule renders the same framebuffer, since each sample's random numbers are seeded from the seed, the pixel and the sample index. This is the medium scene at the benchmark's settings, rendered with the renderer's CLI.
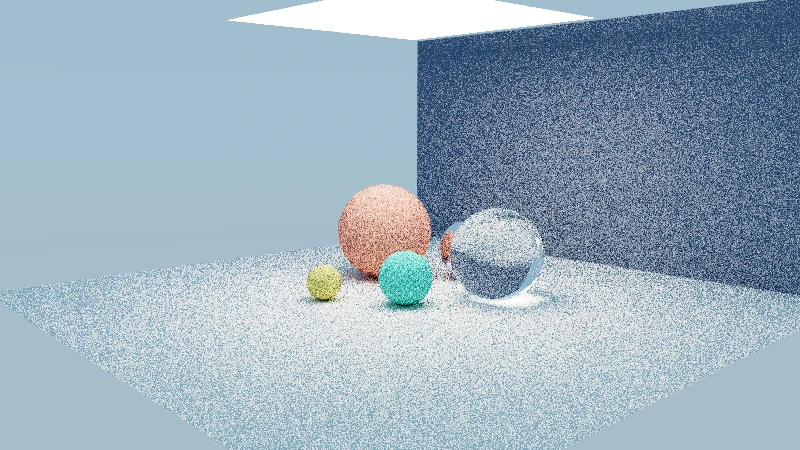
The medium scene, grainy at 16 samples per pixel. Coral, yellow, teal and clear glass spheres sit on a pale floor between a light blue wall and a dark blue wall, under a square ceiling light.
renderer_cli --mode render --scene medium --width 800 --height 450 --spp 16 --depth 8 --tile 32 --seed 123 --threads 16 --schedule dynamic --save medium.png